


The philosophy of relying on a single, unified IP stack to lower your total cost of ownership is not a new concept invented just for the AI era. Semiconductor engineering teams have been weighing the trade-offs of piecemeal versus integrated intellectual property sourcing for decades. In previous process generations, veering away from a unified platform to cherry-pick individual components was often a tolerable compromise. The resulting vendor integration friction was an annoying operational tax, but it was rarely a fatal one.
In the AI era, however, that calculus has fundamentally shifted. As design costs surge toward three-quarters of a billion dollars at the 2nm node, and complex AI workloads push power delivery, operating voltage, and process variation to their absolute physical limits, the financial penalty for execution friction has been dramatically amplified. What was once a manageable integration headache has now become a multi-hundred-million-dollar program killer.
The Silent Economics of Advanced Process Nodes
Historically, engineering teams spent their development cycles comparing individual IP licensing fees line by line. However, as the semiconductor industry accelerates through sub-5nm territories into 3nm and 2nm nodes, that traditional accounting model breaks down completely. Research from International Business Strategies highlights a steep cost trajectory. Where designing a large 28nm SoC from scratch cost roughly $48 million, that figure jumped to $249 million at 7nm, $449 million at 5nm, $581 million at 3nm, and is now projected to reach an astronomical $725 million at 2nm.
At these advanced nodes, the line-item license fee of an individual IP block is entirely dwarfed by the massive financial exposure of late-stage execution failures. Sourcing Foundation IP by assembling logic libraries from one vendor, embedded memories from a second, I/Os from a third, and non-volatile memory from a fourth introduces unverified boundary lines across the silicon layout. Every additional vendor interface represents an active seam where schedule delays and integration mismatches accumulate. Engineering teams operating in this fragmented environment frequently contend with mismatched deliverables and documentation, clashing characterization standards, and multiple support queues between suppliers. Furthermore, when integration hurdles emerge or silicon bring-up encounters unexpected behavior, no single vendor owns the root-cause analysis, resulting in fragmented accountability and overwhelming administrative overhead. When high-performance computing and Edge AI workloads push transistors to their physical limits, these late-stage surprises become exponentially more expensive.
Quantifying the Execution Exposure
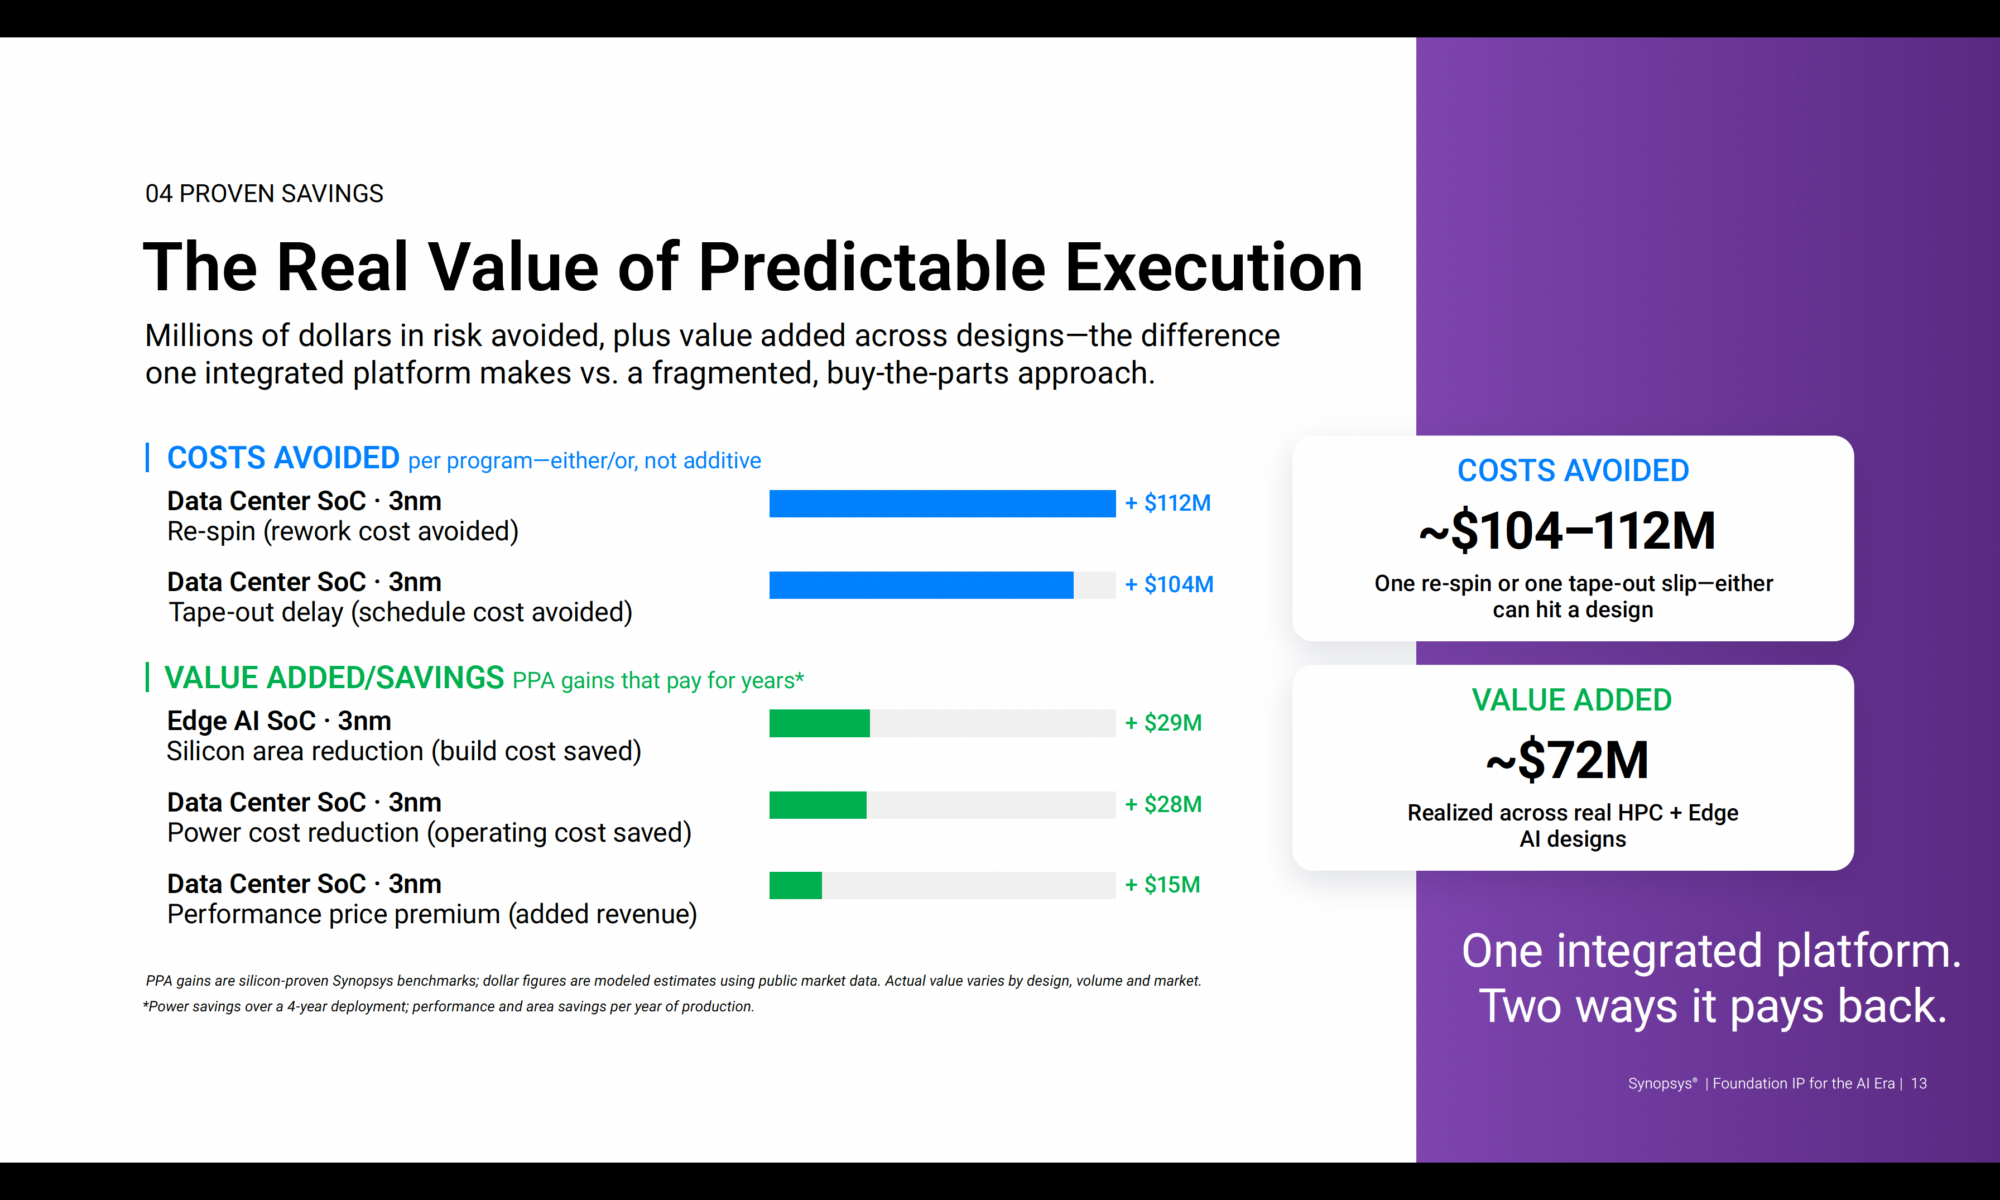
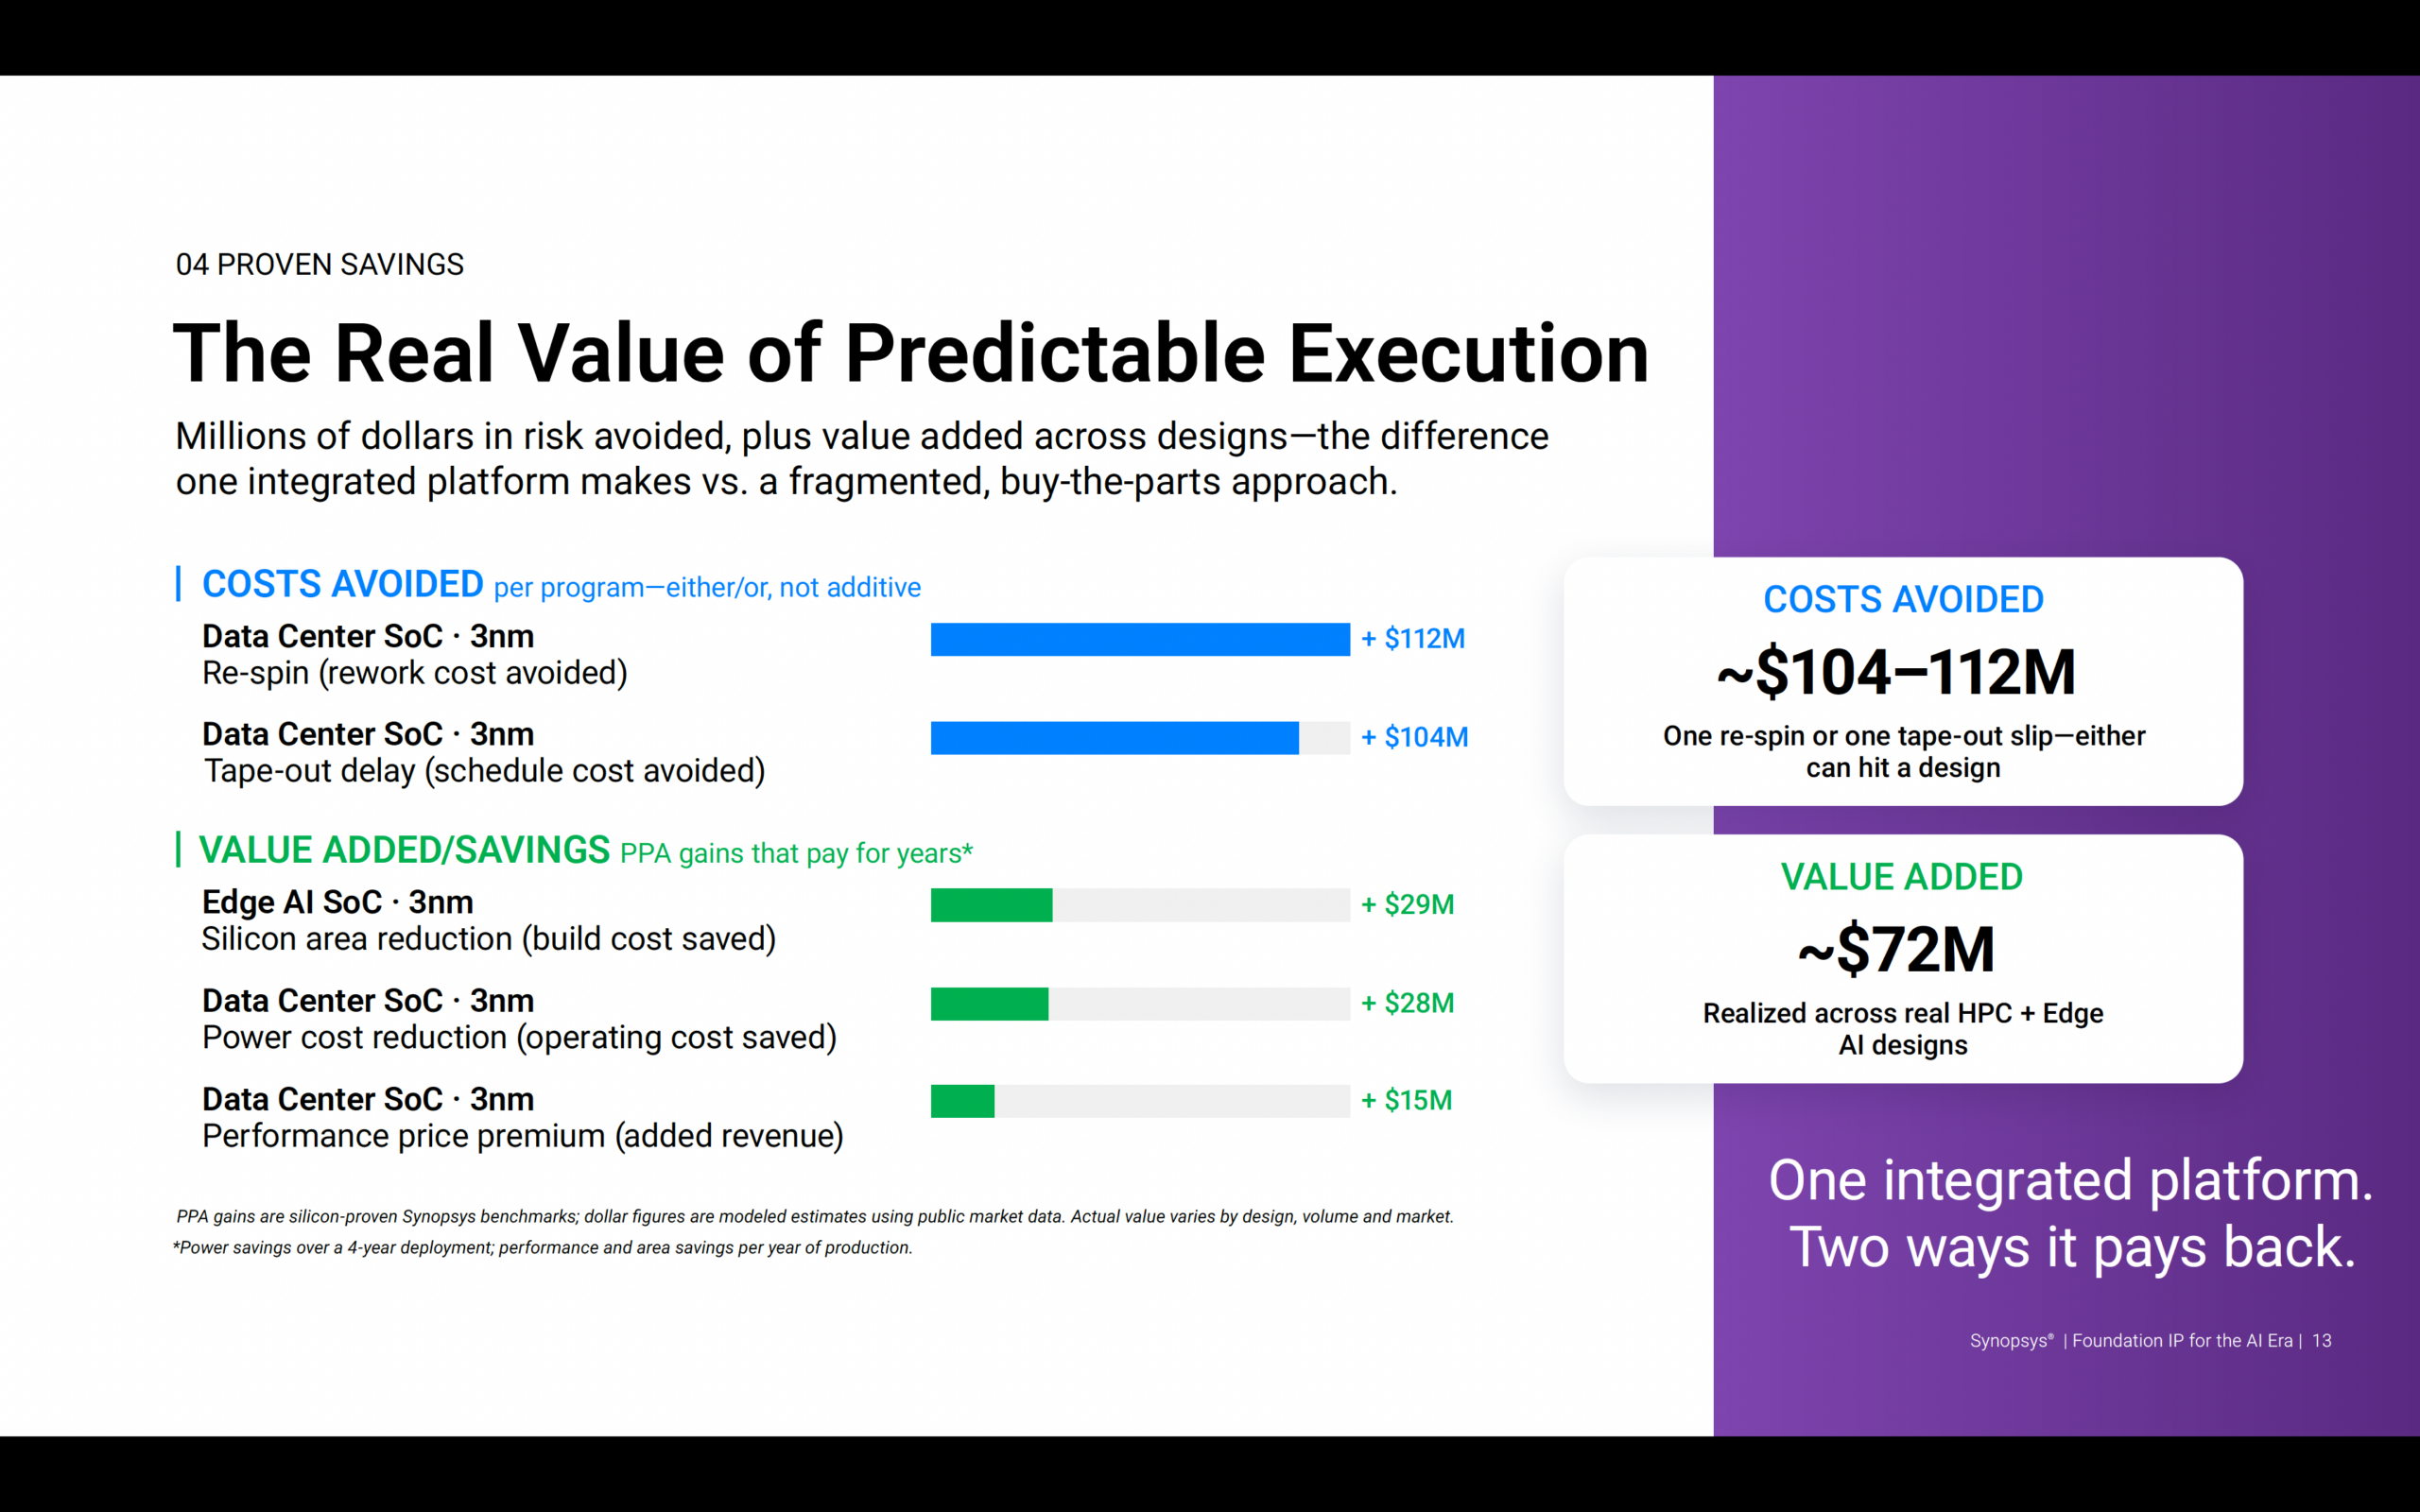
To understand why execution now dictates true total cost of ownership, consider the modeled financial impact of late-stage execution errors on a 3nm Data Center SoC. For a server processor targeting a four-hundred-million-dollar, three-year revenue window, a twenty percent lifecycle delay of approximately 7.2 months puts roughly $80 million in launch revenue at direct risk. When combined with maintaining an engineering team of two hundred developers during the slip, which adds twenty-four million dollars in pure burn rate, the total financial impact reaches one hundred and four million dollars. Missing an initial deployment window often forces a design into a lower-margin quarter or forfeits lead-customer commitments altogether.
The ultimate nightmare scenario remains the cost of a silicon re-spin. If bugs or defectivity require an unexpected re-spin, the direct engineering expense of a fifty percent mask set re-work adds roughly $7.5 million in NRE. However, because a re-spin inherently forces that same 7.2-month schedule slip, the combined exposure swells to approximately $112 million. At advanced nodes, a single unbudgeted re-spin can completely wipe out a product line’s profitability or cause executive leadership to cancel the entire program.
The Single-Platform Advantage and Concrete PPA Returns
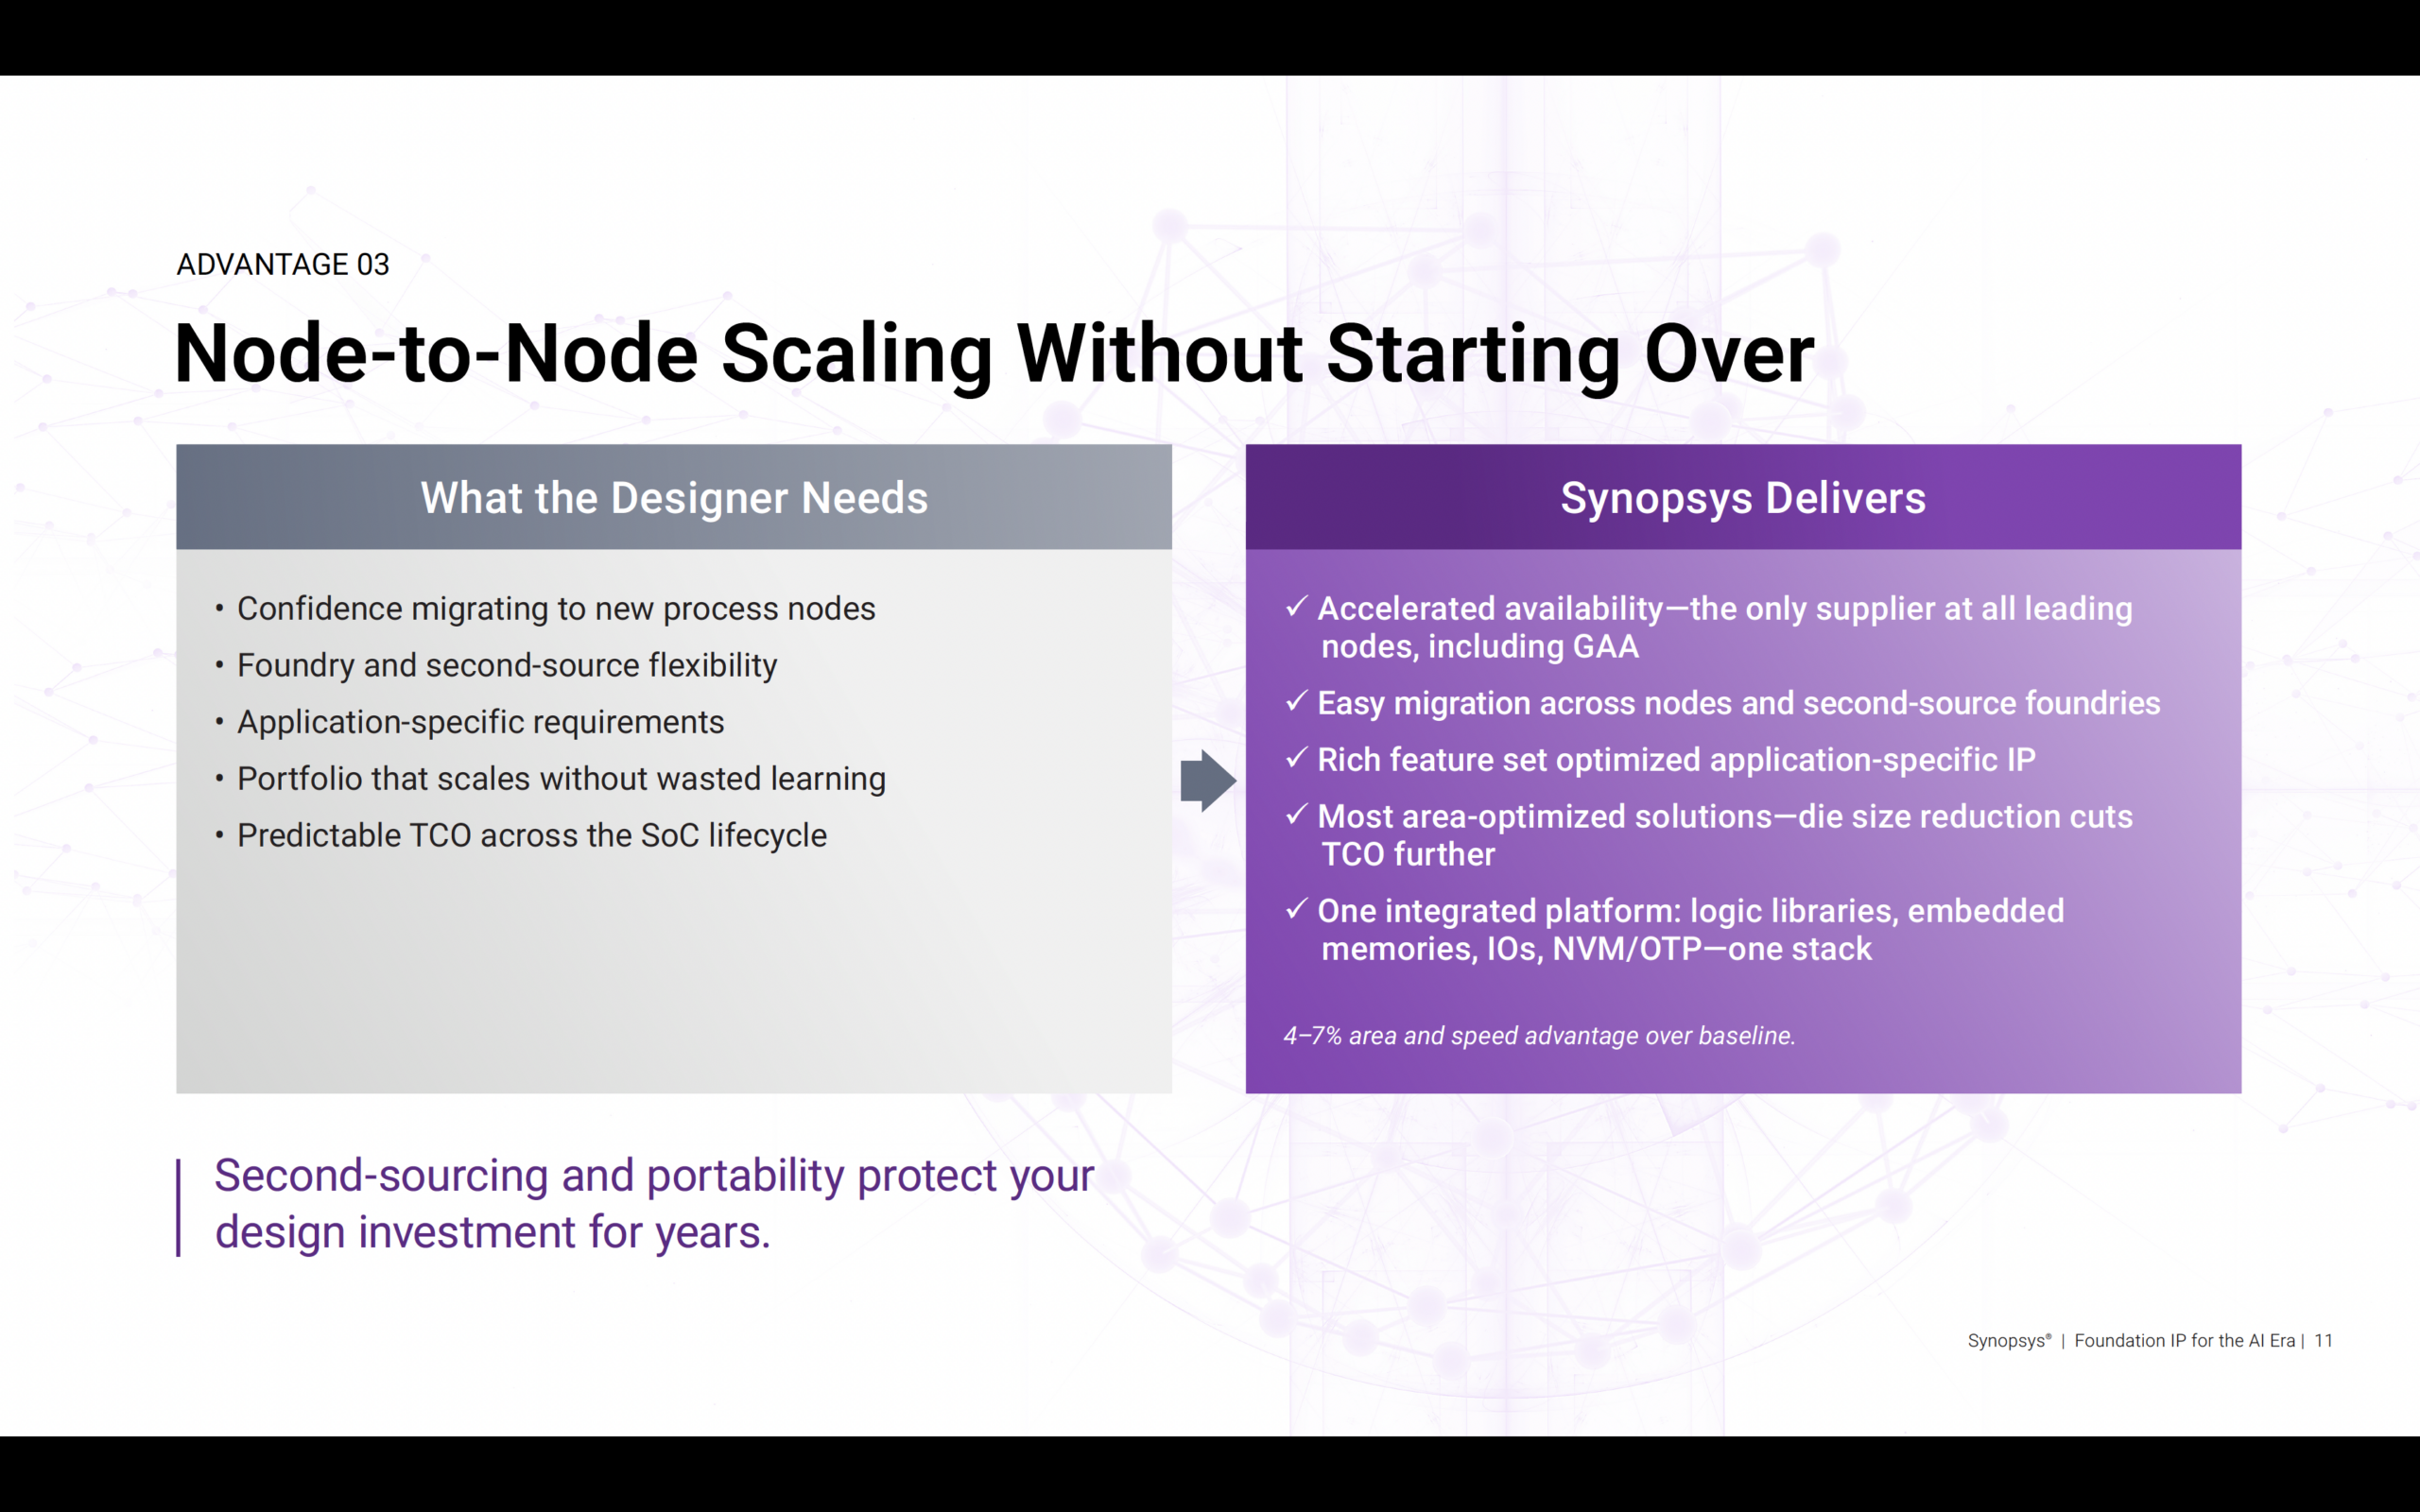
Transitioning from a fragmented basket of parts to a single, integrated Foundation IP platform shifts integration risk back to the IP provider. EDA co-optimized, pre-verified stacks containing logic libraries, embedded memories, I/Os, and NVM OTP eliminate cross-vendor integration seams before they ever reach the design floor. Beyond risk mitigation, co-optimized Foundation IP delivers measurable power, performance, and area returns that compound over production runs. On a 3nm Data Center SoC, a twenty-eight percent reduction in logic library power translates across a hundred-thousand-server deployment into twenty-eight million dollars in saved electricity costs over a four-year lifecycle. Additionally, achieving a six percent performance uplift, assuming a modest three percent price premium, yields fifteen million dollars in added annual revenue across a volume of two-hundred and fifty thousand units per year.
These efficiency gains extend directly into edge applications as well. On a 3nm Edge AI SoC shipping twenty million units annually, an eleven percent reduction in memory area shrinks the overall die size, saving twenty-nine million dollars per year in silicon wafer costs. Synopsys Foundation IP delivers a four to seven percent area and speed advantage over baseline and supports every leading node, including Gate-All-Around architectures. PPA gains are silicon-proven Synopsys benchmarks; dollar figures are modeled estimates based on public market data and will vary by design, volume, and market.
For a comprehensive look at how a unified IP strategy extends beyond Foundation IP to encompass high-speed interface IP, security subsystems, multi-die chiplets, and Silicon Lifecycle Management (SLM), read the SemiWiki post: [The Architecture of Success: Why a Unified Semiconductor IP Strategy Is the Foundation of Modern SoC Design].
Rethinking IP Strategy for First-Pass Success
Sourcing core logic libraries, embedded memories, I/Os, and non-volatile memory is no longer a downstream procurement line item. It is the bedrock of the entire system strategy. Because Foundation IP sets the physical, thermal, power, and voltage boundaries for the entire System-on-Chip, decisions made at this layer dictate what is architecturally possible across the rest of the design. A power reduction in logic libraries or near-threshold voltage tuning does not merely save battery life; it unlocks the power and thermal budget required to deploy high-throughput interface IP like PCIe, CXL, and UCIe chiplets, as well as advanced security subsystems, without hitting a physical thermal wall. Conversely, a mismatch in basic cell characterization or memory timing ripples upward, compromising high-speed interfaces and full-system reliability.
Summary
As design costs approach three-quarters of a billion dollars for a large 2nm SoC, semiconductor business models can no longer absorb integration friction. In the AI era, chip profitability is won or lost in execution, not in individual IP licensing fees. Because Foundation IP is the foundation of everything, getting this baseline layer right is the single most critical decision an engineering leadership team can make. Securing sign-off-ready characterization, enforcing a zero silicon-defect methodology, and establishing single-vendor accountability remains the most predictable path to protecting product margins and ensuring full-system success.
Download the Synopsys eBook “Foundation IP for the AI Era”
Learn more about Synopsys Foundation IP portfolio.
Also Read:
Why Synopsys’ Role in AMD’s Instinct MI455X Matters for AI Infrastructure
Why AI Security Starts at the Chip Level
Overcoming the Edge AI Power Wall with Low-Voltage Foundation IP
Share this post via:


Comments
There are no comments yet.
You must register or log in to view/post comments.