

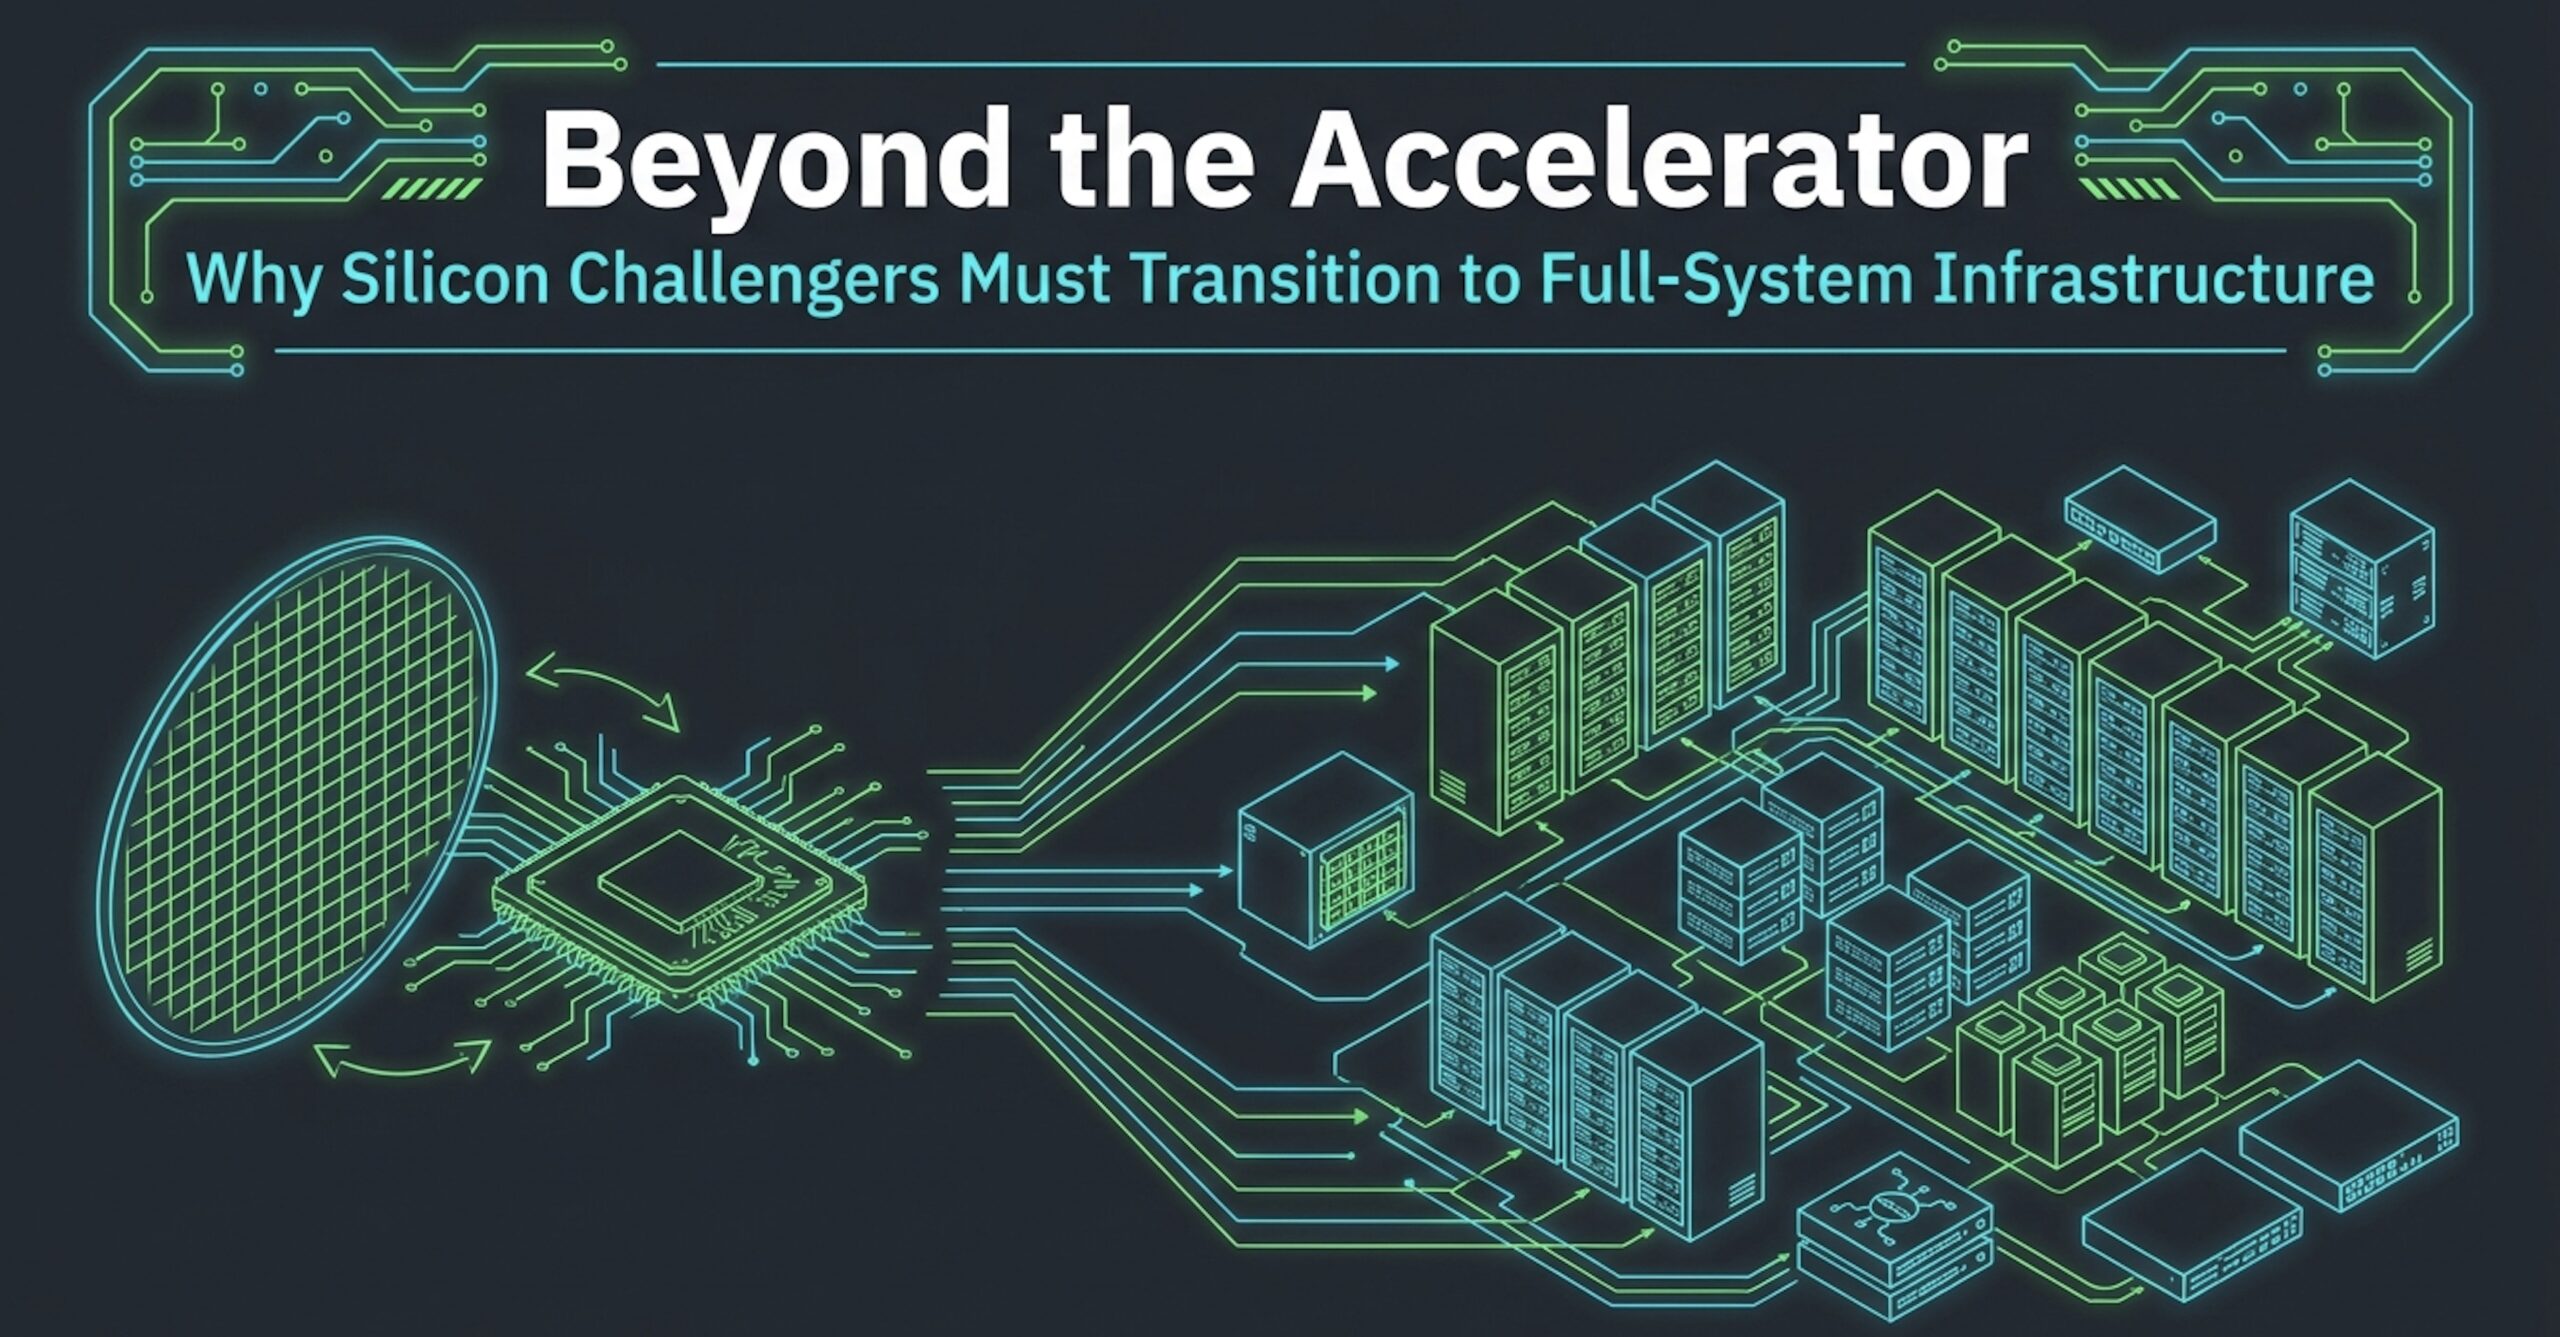
The recent AI Infra Summit was exceptionally jam-packed, filled to the brim with compelling talks, overlapping tracks, and emerging technologies. Amid the noise of the event, there were many excellent presentations detailing the physical realities of scaling hardware. But one presentation in particular caught my attention because it highlighted a major, systemic shift in the market: it introduced another addition to the line of trailblazing, silicon-oriented companies that have realized and made the definitive transition toward true system-level thinking and holistic infrastructure offerings.
That company is Rebellions. Their talk at the Summit and the strategic roadmap they laid out reveals a clear conviction that the AI infrastructure market is quietly outgrowing its honeymoon phase.
For the past few years, the entire industry has been locked in a race to celebrate raw peak performance metrics and laboratory triumphs. But as inference workloads scale up across enterprise ecosystems, the focus of the conversation is shifting. Senior leaders are waking up to a completely different set of metrics: predictable operational costs, system reliability, structural scalability, and the unglamorous realities of day-to-day deployment.
The future of the market does not belong to companies that merely produce fast chips. It belongs to providers capable of orchestrating complete AI infrastructure. By building toward integrated, rack-scale and pod-scale deployments, the industry is anchoring its identity around a broader vision of AI sovereignty. It is about handing organizations total, localized custody over the hardware and software systems running their mission-critical data.
From Silicon to Complete Infrastructure
Deploying enterprise-grade inference is no longer as simple as plugging an accelerator into a PCIe slot and walking away. As models find their way into core production pipelines, the operational topology grows incredibly complex. A viable architecture demands a highly coordinated symphony of specialized hardware, sophisticated model compilation, system-wide orchestration, efficient power management, and dense liquid or air cooling.
Treating these elements as fragmented, standalone procurement decisions is a recipe for operational gridlock. They must be engineered as an integrated, unified topology.
This philosophy explains the aggressive push into multi-rack and pod-scale architectures designed for hyperscale data centers. As inference continues to swallow up the lion’s share of global corporate infrastructure spending, the market is beginning to evaluate silicon through a much harsher lens. The ultimate scorecard is no longer how blazing fast a chip can finish a specific synthetic benchmark, but how much useful, revenue-generating work the system can execute for every dollar and watt consumed.
The Software Strategy: “No Forks”
A great piece of silicon is entirely useless if developer friction keeps it sitting idle in the rack. Historically, hardware challengers have wrecked their own momentum by building proprietary software islands, thereby forcing buyers to learn bizarre new programming languages or maintain specialized toolchains.
The software approach required to break this bottleneck can be summarized in two words: “no forks.”
Instead of hijacking open-source projects to create rigid, proprietary variants that customers must download, test, and patch independently, system-level trailblazers upstream their contributions directly into mainline repositories. They eliminate the traditional onboarding penalty by embedding execution logic natively into the foundations of existing open-source giants including PyTorch, Hugging Face, Arm, and Red Hat OpenShift.
For an enterprise tech organization, this is a massive operational victory. Deploying an alternative accelerator is rarely just a line-item hardware expense. It typically forces an organization to absorb the hidden costs of retraining engineers, rewriting software competencies, and engineering custom deployment procedures. By native-fitting directly into standard open-source ecosystems, greater compatibility effectively erases that friction.
Ultimately, introducing an alternative engine to the data center environment is no longer just a chip decision but rather an ecosystem decision.
Where does the math actually net out when you take this integrated system approach into the data center? In Part 2 of this series, we break down the contrast between laboratory benchmarks and real production economics as presented by Rebellions, alongside a look into multi-megawatt heterogeneous deployments.
[READ PART 2 HERE: Tokens Per Watt Over Peak Performance: Retrofitting Heterogeneous Silicon for Production Inference][Will be linked after Part 2 is published]
Share this post via:


ASML Has High-NA and Chipmakers Can’t Say No