

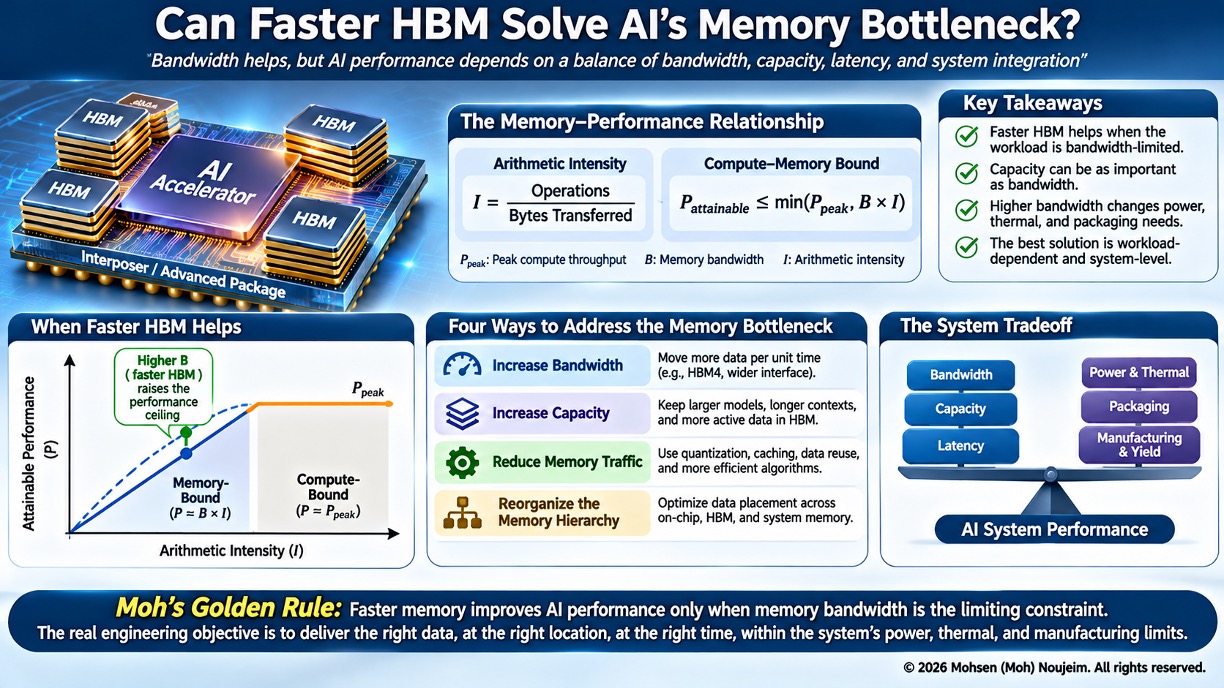
Why bandwidth alone cannot determine the performance of the next generation of AI accelerators
High-bandwidth memory is entering another phase of rapid development. HBM4 increases interface width and available bandwidth, while custom HBM architectures create opportunities to optimize how memory connects to AI accelerators.
These developments address an important limitation of modern AI computing: increasingly powerful processors cannot sustain their theoretical performance when the required data cannot be delivered efficiently.
But there is a more fundamental question.
If HBM bandwidth continues to increase, will AI applications become proportionally faster?
Not necessarily.
The answer depends on which part of the memory system limits the workload. Bandwidth, capacity, latency, data reuse, and communication beyond the local accelerator impose different constraints.
Faster HBM can relieve one bottleneck while exposing another.
Understanding that distinction is becoming essential to both AI accelerator architecture and advanced semiconductor packaging.
1. Why HBM Bandwidth Matters
Modern AI accelerators perform enormous numbers of mathematical operations. However, those operations depend on a continuous supply of model weights, activations, attention data, and intermediate results.
HBM provides high bandwidth through a wide interface and vertically integrated DRAM stacks located close to the processor.
This physical proximity allows the accelerator to access much more memory bandwidth than would typically be available through conventional external memory interfaces.
The benefit is particularly important when an application must move large volumes of data relative to the amount of computation performed on that data.
One useful way to describe this relationship is arithmetic intensity.
Equation (1) — Arithmetic Intensity
Equation (1) — Arithmetic Intensity
I=N_operations/V_{memeory Eq. 1
where Noperations is the number of operations performed and Vmemory is the volume of data transferred, in bytes, between the processor and the memory level being evaluated.
A workload with low arithmetic intensity moves relatively large amounts of data for each operation. Its performance may be limited by memory bandwidth.
A workload with high arithmetic intensity performs more operations for each byte transferred. It is more likely to be limited by computational capability.
The distinction is central to determining when increasing HBM bandwidth creates value.
Consider a simplified accelerator with peak computational throughput (P_{\mathrm{peak}}) and sustained memory bandwidth (B_{\mathrm{sustained}}).
The roofline relationship expresses an upper bound on computational throughput.
Equation (2) — Roofline Performance Bound
P_attainable <= min P_peak, B_sustained . I Eq. 2
where P_peak is peak computational throughput, B_sustained is sustained memory bandwidth, and (I) is arithmetic intensity measured against that same memory level.
The relationship is dimensionally consistent because memory bandwidth, measured in bytes per second, multiplied by arithmetic intensity, measured in operations per byte, produces operations per second.
This is a performance bound, not a prediction of achieved application throughput. Actual performance also depends on implementation efficiency, memory-access behavior, synchronization, and other system effects.
If a workload is strongly bandwidth-limited, increasing sustained bandwidth can improve its performance ceiling.
Once the workload approaches the computational limit, however, more bandwidth provides diminishing benefit.
This is the first reason faster HBM does not automatically produce faster AI systems.
2. AI Training and Inference Do Not Have the Same Memory Problem
The value of additional bandwidth changes significantly across workloads.
During AI training, large matrix operations can reuse data extensively, especially when computations are arranged to maximize the efficiency of accelerator resources.
Some operations are compute-bound, while others are limited by memory traffic, communication, or the management of intermediate data.
Training performance therefore depends on the balance among computational throughput, memory access, and communication across multiple accelerators.
Inference introduces another distinction.
The prefill phase processes incoming tokens and builds the information required for subsequent generation. Large, parallel matrix operations can achieve substantial data reuse and may be compute-bound.
The decode phase generates subsequent tokens and frequently has a different computational structure.
Depending on model architecture, batch size, context length, and implementation, decode may require repeated movement of model weights or attention data while performing comparatively less computation.
In these conditions, additional HBM bandwidth can substantially improve token-generation throughput.
However, this benefit is not uniform.
Larger batches can increase data reuse and computational intensity. Long-context attention can introduce substantial key-value cache traffic. Speculative decoding and other execution techniques may also change which resource limits performance.
Consequently, there is no single bandwidth requirement that describes all AI inference workloads.
The engineering question is not simply how fast the HBM interface can operate.
It is whether the workload can use that additional bandwidth efficiently.
3. The Capacity Problem: Faster Memory Is Not Necessarily Enough Memory
Bandwidth determines how quickly data can be transferred.
Capacity determines how much data can remain in a particular memory tier.
These are related but distinct constraints.
An AI model must accommodate its required weights, activations, temporary data, and relevant inference state within the available memory hierarchy.
For large-language-model inference, the key-value cache can become a significant consumer of HBM capacity, particularly as context length and concurrent request counts increase.
If the working set exceeds available HBM capacity, the system may need to distribute data across additional accelerators, move selected data into another memory tier, or change how it schedules and processes requests.
These choices can introduce communication overhead, additional latency, or reduced computational efficiency.
A faster HBM interface does not eliminate those costs.
Consider two hypothetical accelerator configurations.
One provides higher HBM bandwidth but limited capacity.
The other provides moderately lower bandwidth with sufficient capacity to retain the entire required working set locally.
For a workload that fits within both configurations, the first system may benefit from greater bandwidth.
For a workload that exceeds the first system’s capacity, the second may avoid expensive offloading or additional distributed communication.
The faster memory interface can therefore belong to the slower overall system.
This is not an argument that capacity is always more important than bandwidth.
It is an argument that memory performance depends on the relationship between working-set size, bandwidth, and placement within the memory hierarchy.
4. Four Different Ways to Address the Memory Bottleneck
Accelerator designers have several possible approaches to increasing effective memory performance.
Each addresses a different part of the problem.
Approach A: Increase HBM Bandwidth
The most direct approach is to increase the amount of data transferred per unit of time.
Wider interfaces, higher signaling rates, and improvements in memory architecture can raise aggregate bandwidth.
This benefits applications whose performance is limited by sustained memory traffic and whose computational resources can use the additional data.
However, increased bandwidth can require additional interface resources, power-delivery capability, routing infrastructure, and thermal management.
The system must also demonstrate that the intended operating bandwidth can be sustained under the relevant workload and environmental conditions.
Approach B: Increase HBM Capacity
Another approach is to increase memory density or the number of memory stacks associated with an accelerator.
Additional capacity can support larger models, longer contexts, more concurrent requests, and reduced dependence on slower memory tiers.
But increasing capacity is not free.
Additional stacks consume package area, create routing and power-delivery requirements, and contribute to thermal and manufacturing complexity.
More capacity also does not guarantee improved throughput if the workload remains limited by bandwidth or computation.
Approach C: Reduce Memory Traffic
A third approach is to reduce how much data must move between memory and compute.
Techniques such as quantization, caching, improved attention algorithms, data reuse, and workload-aware scheduling can lower memory traffic or increase useful computation per transferred byte.
This can be particularly powerful because it improves the efficiency of existing bandwidth rather than relying exclusively on faster physical interfaces.
The tradeoff may involve numerical precision, additional computation, software complexity, cache-management overhead, or workload-specific behavior.
The objective is to reduce unnecessary movement without compromising the application’s required performance and accuracy.
Approach D: Reorganize the Memory Hierarchy
A fourth approach is to change where data resides and how it moves among memory tiers.
On-chip SRAM, local HBM, memory attached to other accelerators, and host memory provide different combinations of bandwidth, capacity, latency, and cost.
Placement decisions can determine whether frequently accessed information remains near compute or requires movement through additional interfaces.
This becomes increasingly important as AI systems scale beyond one accelerator.
A memory hierarchy optimized for one workload may not be optimal for another.
The preferred architecture depends on the working set, access patterns, communication requirements, and the cost of moving data between tiers.
These four approaches are not mutually exclusive.
A successful AI system may require more bandwidth, greater capacity, better data reuse, and improved placement decisions simultaneously.
5. Why Faster HBM Can Move the Bottleneck
Suppose an AI workload requires a fixed amount of memory traffic per completed operation.
Increasing sustained memory bandwidth reduces the time needed to transfer that data, assuming the transfer is bandwidth-limited and the workload can utilize the increase.
But once memory transfer time falls below another limiting operation, further bandwidth improvements may no longer determine overall performance.
For example, reducing HBM access time may expose a limitation in computational throughput, synchronization, inter-accelerator communication, or software scheduling.
Similarly, increasing local memory bandwidth can make remote data movement more visible as a percentage of total execution time.
This is an important architectural consequence.
Improving one part of the memory system changes the relative importance of the remaining parts.
The correct engineering analysis must therefore identify the dominant bottleneck before and after the proposed memory improvement.
A comparison based solely on peak HBM bandwidth cannot establish the resulting application-level speedup.
The relevant measures include actual bandwidth utilization, execution time, achieved token throughput, latency, working-set residency, and system energy consumption under representative workloads.
6. The Power and Thermal Consequences of Higher Bandwidth
Higher bandwidth also changes the physical demands on the memory subsystem.
The total power associated with memory operation depends on several factors, including DRAM activity, interface operation, controller logic, data movement, and operating conditions.
An architecture delivering more bandwidth may improve energy efficiency per transferred bit while still increasing total memory-subsystem power under some workloads.
Therefore, bandwidth and power must be considered together.
The relevant efficiency measure is not simply the memory system’s peak transfer rate, but the energy required to deliver useful data under operating conditions.
Thermal behavior introduces further complications.
HBM stacks contain multiple vertically integrated memory dies connected through high-density interconnect structures.
Heat generation and heat removal depend on stack geometry, operating activity, neighboring accelerator power, material properties, and the surrounding package architecture.
A high-performance accelerator can create demanding thermal conditions for nearby memory, while increased memory activity contributes its own heat.
If thermal or power constraints reduce sustainable operating performance, the achieved bandwidth may fall below the nominal interface capability.
This creates a distinction between advertised bandwidth and bandwidth that can be maintained within the product’s qualified operating conditions.
For advanced packaging engineers, this is where memory architecture becomes a system-integration problem.
7. What Changes at the Package Level?
Increasing HBM performance affects more than the DRAM stack.
The accelerator package must support the corresponding electrical interfaces, power-delivery structures, thermal paths, and mechanical requirements.
Higher aggregate bandwidth may require changes in signal organization, routing resources, interface placement, or interconnect density, depending on the memory generation and selected architecture.
These requirements interact with the practical limits of interposer size, substrate technology, package geometry, power distribution, and thermal management.
Adding memory stacks to increase capacity creates another set of constraints.
More stacks require additional physical area and may change signal routing, power distribution, assembly sequence, thermal interaction, and test strategy.
The preferred memory configuration must therefore be evaluated as part of the complete package architecture.
A design that improves the theoretical memory specification may introduce packaging costs or constraints that reduce its practical system benefit.
This is especially relevant for increasingly heterogeneous AI packages where compute, memory, and high-speed communication compete for limited physical resources.
8. Manufacturing and Qualification Cannot Be Separated From Performance
The next challenge is manufacturing repeatability.
A nominal memory interface specification describes intended capabilities, but actual products must satisfy those requirements after fabrication, stacking, assembly, and qualification.
HBM manufacturing depends on controlled DRAM fabrication, vertical interconnect formation, die alignment, bonding integrity, electrical testing, and thermal reliability.
As memory stacks become more demanding, manufacturing variation can influence electrical margins, thermal behavior, and the operating characteristics of the completed package.
This does not mean that higher bandwidth necessarily causes lower yield.
It means that the applicable manufacturing process must demonstrate sufficient capability for the selected design requirements.
Engineers must distinguish the nominal performance of a memory architecture from the performance supported by actual manufacturing and product evidence.
For example, two implementations may satisfy the same nominal bandwidth specification while demonstrating different power consumption, operating margins, or thermal behavior.
Those differences become important when integrating multiple memory stacks with a high-power accelerator.
The engineering challenge is to sustain the required bandwidth, capacity, and reliability across the intended operating envelope while controlling manufacturing cost.
This is why HBM performance cannot be judged by interface speed alone.
9. What Should the Industry Optimize Next?
The next phase of HBM development should focus on effective memory performance rather than peak bandwidth alone. Higher bandwidth delivers the greatest benefit when memory transfer is the dominant workload constraint. When capacity, latency, computation, or interconnect communication becomes limiting, other architectural improvements may provide greater value.
The preferred approach is to match memory bandwidth and capacity to workload requirements, improve data reuse and placement, and evaluate the resulting system within its power, thermal, packaging, and manufacturing constraints.
The engineering objective is not to maximize every memory specification independently, but to achieve the best sustained AI performance for the intended workload.
10. The Engineering Takeaway
HBM has become one of the defining technologies of modern AI infrastructure because it enables powerful processors to access large quantities of data at high speed.
As the industry moves toward wider interfaces, greater capacity, and more customized memory architectures, the performance opportunity remains substantial.
But bandwidth is only one dimension of the memory problem.
The complete system must balance bandwidth, capacity, latency, computational intensity, energy consumption, packaging constraints, and manufacturing capability.
Faster HBM can remove a critical bottleneck. It cannot guarantee that another bottleneck will not take its place.
The next generation of AI accelerators will be defined not only by how quickly their memory can transfer data, but by how effectively the entire system can use that data.
Moh’s Golden Rule: Faster memory improves AI performance only when memory bandwidth is the limiting constraint. The real engineering objective is to deliver the right data, at the right location, at the right time, within the system’s power, thermal, and manufacturing limits.
References
- NVIDIA, Inside NVIDIA Rubin GPU Architecture: Powering the Era of Agentic AI, July 2026. https://developer.nvidia.com/blog/inside-nvidia-rubin-gpu-architecture-powering-the-era-of-agentic-ai/
- NVIDIA, Co-Designing AI Model Attention for Fast, Interactive Long-Context Inference, 2026. https://developer.nvidia.com/blog/co-designing-ai-model-attention-for-fast-interactive-long-context-inference
- NVIDIA, AI Model Co-Design: Hardware-Friendly LLM Design, 2026. https://developer.nvidia.com/blog/ai-model-co-design-hardware-friendly-llm-design/
- I/O for LLM Inference: A Survey of Storage and Memory Bottlenecks, Artificial Intelligence Review, 2026. https://link.springer.com/article/10.1007/s10462-026-11651-1
Also Read:
CTO Interview with Juan Rey, senior VP and general manager of Calibre and CTO of Siemens EDA
CPO’s Next Challenge: Turning Optical Performance into Manufacturable Systems
Three-Dimensional Chess Anyone? The Challenges of Power Integrity for Multi-Die Designs
Share this post via:


Jensen Huang and the Cost of Unchecked Influence